Tuesday, October 23, 2012

Key words through graph entropy Hierarchical clustering

In the last post I showed how to extract key words from a text through a principle called graph entropy.
Today I'm going to show another application of the graph entropy in order to extract clusters of key words.
Why
The key words of a document depict the main topic of the content, but if the document is big, often, there are many different sub topics related to the main.
In this perspective, a clusters of keywords should make easier for the reader the identification of the key points of a document.
Moreover, imagine to implement a search engine based on clusters of relevant words instead of the common indexing of atomic words: it enables documents comparison, taxonomies definition, and much more!
How
The definition of graph entropy I'm studying on, assigns to each word of the document a relevance score and a sub graph of words topologically closed to it.
The clustering should maximize the relevance score obtained merging two words in the same cluster.
It's easy to understand that we have to face a combinatoric maximization problem.
The idea is to take advantage of the Simulated annealing (a bit revisited and adapted to the scope) in order to identify sub-optimal merging solution at each step of the merging phase of the hierarchical clustering.
Experiment
I decided to adopt as document test the complete version of the file we used in the last post: Nuclear_weapon.
Here you are the clusters of first 100 relevant words extracted:
The three clusters obtained.

It's interesting highlight the following considerations:

  • The first cluster merged together words as "material,uranium, plutonium, isotope" and "war, attack, arm", and also "proliferation, movement, control, development".
  • The second cluster (which has the lowest rank) aggregates words as "japan, japanese, place, israel, iraq,american", and "ton, tnt, yeld"  
  • The third cluster (which has the highest rank) describes quite well the primary topic, merging all the most important words of the document! 

Of course, the procedure is still in "incubator" phase, and the accuracy of the clusters rests on the performance of the Annealing clustering (...maybe different algorithms in this context perform better... but just to show a rough solution I guess it's enough :D)
This is the optimization process for the last merging stage (I presume that temperature schedule requires an adjustment):
Optimization curve through Simulated Annealing Hierarchical Clustering (last merging stage)

Next steps:
Looking forward to receive comments, and suggestions.
...It would be interesting using such methodology to create a new kind of full text search engine, totally independent by frequency of the words and frequency of visits.


The doc
here you are the document parsed and colored through the clustering assignment (have been highlighted just the first 100 relevant features ranked through the Graph Entropy method).

http://www.ziddu.com/download/20701582/nuclearWeapons.pdf.html
Stay tuned
cristian.

Monday, September 24, 2012

Graph Entropy to extract relevant words

I would share with you some early results about a research I'm doing in the field of "graph entropy" applied to text mining problem.

There are many definitions of graph entropy, my favorite is very well described in the work of J.Körner: Coding of an information source having ambiguous alphabet and the entropy of graphs (1973).

Why Graph Entropy is so important?
Based on the main concept of entropy the following assumptions are true:

  • The entropy of a graph should be a functional of the stability of the structure (so that it depicts in some way the distribution of the edges of the graph).
  • Sub sets of vertexes quite isolated from the rest of the graph are characterized by a high stability (low entropy).
  • It's quite easy use the entropy as a measure for graph clustering.
As you can imagine a smart definition of graph entropy can be helpful in many problems related to text mining.

Let's see an application of graph entropy to extract relevant words in a document.

The experiment as been done using the first section of the definition of "nuclear weapons".

Results
Graph Entropy:
In red have been highlighted the relevant words extracted through Graph Entropy
Here you are the words extracted (first 25th) - In red I depicted words that in my opinion shouldn't be selected:
weapon, reaction, nuclear release, consider, acknowledge, explosive, weaponsa, detonate, test, ton, bomb, energy, tnt, first, possess, small, device, unite, hiroshima, chronologically, thermonuclear, force, nagasaki

Frequency based:
In red have been highlighted the relevant words extracted through Frequency relevance.
Words extracted through the frequency relevance: 
nuclear, weapon, bomb, fission, test, possess, bombing, detonate, state, unite, tnt, ton, first, energy, release, acknowledge, weaponsa, status, japan, nagasaki, hiroshima, japanese, name, code, type

Closeness Centrality:
In red have been highlighted the relevant words extracted through Closeness Centrality method.

Words extracted through the frequency relevance: 
nuclear, weapon, detonate, possess, nagasaki, first, thermonuclear, small, force, estimatedebut, fabricate, succeed, radiation, tnt, acknowledge, consider, believe, hiroshima, know, nation, boy, explode, matte, date.

Considerations:

  • The method based on graph entropy seems provide the more accurate results (5 errors respect 9 and 11 of the other methods).
  • The graph entropy depicts better the core of the graph containing the relevant words.
  • I tried to expand the number of relevant features and the accuracy of the other two methods tends to worsen quickly:

  • First 40 relevant words using Graph Entropy, Frequency method and Closeness Centrality.
    Notice how the graph Entropy preserves better the core of the graph respect the other two methods.

    Stay tuned
    cristian

    Sunday, August 12, 2012

    Function minimization: Simulated Annealing led by variance criteria vs Nelder Mead

    Most of the datamining problems can be reduced as a minimization/maximization problem.
    Whenever you are looking for the best trade off between costs and benefits you are solving a minimization problem.
    Often the number of the variables that affects the cost function is high and the domain of these variables is in a dense set and, last but not least: in the real world problem often, you have no clue about the analytical form of the function.
    Formally such problems belong to the multidimensional unconstrained optimization family.
    Examples
    Let's consider  easy scenarios where the function cost is conditionated just by two parameters.
    Schaffer f6 function: in the contour plot  dark purple to depict local minimums.


    Another function where minimum ischaracterized by two valleys 

    This function presents several local minimums well depicted in the contour plot

    This function is characterized by a several local minimums having high range of values 

    As you can see the above problems have in common a massive presence of local minimum :).
    Let's see how to handle these problems through an approach that I define hybrid, that is, obtained mixing different methods and properties.
    Simulated Annealing (SA) "variance based" approach
    Disclaimer: I had no the time to check whether this method has been already published somewhere. The underlying idea is quite simple, so I would assume that someone has already spent time in proofing convergence and better variations (and actually I don't think is a rocket science proof it).
    SA, belongs to the family of numerical method based on "search strategy" and its convergence requirements are related to the stationary conditions inducted by the underlying markovian process.
    In a former post I showed an its application in a discrete domain, where at each iteration we chose the next candidate solution by comparison with the current solution. The new solution was found "fishing randomly" a candidate in a discrete space.
    In the above problems the solution space is continuos, so we need a smart strategy to extract the new candidate. Let's see my approach!
    Variance trick 
    Let's consider a sampling in two different region of a function f :
    • sampling_1 in a region having a smooth minimum and evaluate such points
    • sampling_2 in a region having a spiky minimum and evaluate such points
    Take now the variance of these evaluated sets.
    How does the variance of f(sampling_1)  change respect the variance of f(sampling_2)?  
    Here you are the answer:
    As you can see the variance can be used as indicator of a minimum region of the cost function.
    Instead of explore randomly the solution space, the approach I propose is led by the variance used as  above. 
    What happens if the smooth valley is a global minimum?
    There are two intuitive factors to avoid that the algorithm jams in a local minimum:
    1. The acceptance law admit also pejorative solutions.
    2. The sampling procedure moderate by variance (if the variance is chosen high enough) allows explorations of better regions.

    The algorithm

    The meta code of the Simulated Annealing based on variance criteria
    Many optimizations can be done to the algorithm.
    For instance we could condition the annealing procedure only if the
    argMin(evaluate(f,newSet)) > argMin(evaluate(f,curset))

    Tests
    Let's see how the approach works.
    As usual, all my experiments are compared with other techniques. In this case I chose as comparative method the well known "Nelder Mead" method.
    I tried to optimize the Nelder Mead method playing around its param setting: shrink ratio, contraction ratio and reflection ratio.
    All experiments have been done using the same initial points.
    For the Nelder Mead method I plotted just the unique solutions found.
    The approach I propose has been led using always the same setting (3000 cycles, variance sampling = 0.75).
    Experiment 1.
    On the left side it has been represented the solution found by Nelder Mead method.
    On the right side the solution found by the SA presented in this post: the blue point depicts the starting point and the red point depicts the solution found.
    The last chart shows the space solution explored.
    Notice that method found a better solution respect Nelder Mead approach. 

    Experiment 2
    On the left side it has been represented the solution found by Nelder Mead method.
    On the right side the solution found by the SA presented in this post: the blue point depicts the starting point and the red point depicts the solution found.
    SA found a better solution in really few steps.

    Experiment 3
    On the left side it has been represented the solution found by Nelder Mead method.
    On the right side the solution found by the SA presented in this post: the blue point depicts the starting point and the red point depicts the solution found.
    This experiment shows once again the good performance of this approach even if the problem is very challenging!

    Experiment 4
    On the left side it has been represented the solution found by Nelder Mead method.
    On the right side the solution found by the SA presented in this post: the blue point depicts the starting point and the red point depicts the solution found.
    The convergence, as shown above, has been reached very quickly.

    Conclusion
    The approach seems promising and works well in different contexts:  I'm quite sure that many improvements can be implemented.
    I'm looking forward to receive your comments, ideas and other comparative tests.

    Stay tuned!

    cristian

    Tuesday, July 10, 2012

    Data Mining: Tools and Certificates

    As member of many Linkedin groups related to data mining & text mining I read many threads related to certificates that should help either in job seeking and consolidating curriculum, and many other threads about miraculous tools able to solve whatever problem.
    Is being certified really worth it?
    In my experience I think that a certificate in a specific data mining tool could be a positive point on the curriculum, but it doesn't really help to improve your knowledge on the field.
    Let me explain better (which is not easy with my bad English): The certificates system is a market and its target is to generate profit or to promote products.

    Data mining tools
    My question is: do you really think that can exist a tool able to embrace all aspects related to data mining?

    I guess that the number of problems data mining related are so high that maybe we could use the Cantor diagunalization to proof that are uncountable :)


    In my opinion is too naive the common thought that through a software, clicking here and there you can obtain tangible benefits in mining your data.
    The "data mining" definition has been created by marketing industries just to summarize in a buzz word  technics of applied statistics and applied mathematics to the data stored in your hard disk.
    I don't want say that tools are useless, but it should be clear that tools are only a mean to solve a problem, not the solution.
    • In the real world the problems are never standard and really seldom you can take an algorithm as is to solve them! ...maybe I'm unlucky but I never solved a real problem through a standard method.
    • The tool X is able to load Terabyte of data. And so what? A good data miner should know that you cannot consider the entire population to analyze a phenomena, you should be able to sample your population in order to ensure the required margin of accuracy! ... this technic is simply called Statistic!
    • If you really want to claim "I know very well this approach", you must be able to implement it by your self: only implementing it by your self you can deeply understand in which context the algorithm works, under which conditions it performs better than other tools and so on. Don't rely only on one paper that compare few techniques: if you change just one of the conditions the results are terrible different.
    • Without theory you cannot go deep: Let's consider a tool as Mathematica or R or ... These tools allow the user to have access to a large library of pre defined algorithms and routine, they provide visualization functions to show results in a fancy way, and last but not least they provide a complete language programming to code whatever you want. I love them, but I couldn't do anything without the theory behind the problem. Mathematica can provide me the algorithm to cluster a data set through k-means: but how can I be sure that it is the right algo for your problem? (click here to have a demo).
    Actually I would prefer attend a course to deepen some aspects of multivariate statistic or seminars on new methodology to solve some problem respect pay plenty money to know every single detail of a tool, that maybe will not be in the market in the next 5 years.

    I know that the companies often are looking for certified guys on a famous tool just because they bought it and they need to reduce the time to "integrate" a new resource on a team. Fair enough! ...but I think it is ridiculous require certificates as strict requirement!
    I'm really curious to know your experiences and opinions.
    cristian


    Tuesday, July 3, 2012

    Simulated Annealing: How to boost performance through Matrix Cost rescaling

    One of the most widely algorithm used in Machine Learning is the Simulated Annealing (SA).
    The reason of its celebrity lays in:
    • Simplicity of implementation
    • broad spectrum of applicability
    There are many implementations of it available for almost all languages, and many books and papers on the topic; personally the best book I would like to suggest is the Simulated Annealing and Boltzmann Machines: A Stochastic Approach to Combinatorial Optimization and Neural Computing wrote by Korst & Aarts.

    The problem
    In this post I'm going to describe a very canonic combinatoric problem (NP hard complexity) often approached through annealing methods: the complete Asymmetric Travelling Salesman Problem (ATSP).
    The ATSP problem, as you know, can be taken as base to model several problems as for instance network routing problems, chemistry and physics problems. The ATSP is so charming (at least for me) because the nature of the problem is very easy and the way to find out the best solution is extremely trivial: you have to explore all the possible solutions!
    The only problem is the number of solutions you have to compare:
    • with 10 towns you have to explore ~ 3.6*10^6 solution.
    • with 50 towns you have to explore ~ 3 *10^64 solution.
    In the past (I'm not aware if it is still open) there were many competitions to find the best solution of the asymmetric and complete TSP with more than 30000 towns.

    ...Considering the time required to obtain the optimal solution, in many cases a sub optimal solution obtained exploring less than 1% (as usually happens with SA) of the solution space could be enough!


    The experiments
    I considered two instances of the problem, the first one with 10 towns and the second one with 50 towns.
    Even if for this kind of problem there are more efficient algorithms to face TSP, I chose the simulated annealing just to show how versatile it is and to show how much the rescaling operation is essential in order to maximize the performance of your algorithm. 

    Why rescaling? (I'll try to be technical as little as possible)
    The SA bases its powerful on the ability to overcome the local minimum through the acceptance at time "t" of a bad solution respect a better solution found at the time "t-1". It assigns an acceptance probability based on the sigmoidal function that decrease if the cost of the new solution is higher respect the current solution.
    So if the cost distance between the current solution and the new solution is very high, the acceptance probability will be very small.
    This probability is mitigated by the temperature schedule that allow more acceptance rate (of bad solutions) when the temperature of the system is high, and it is reduced once the temperature of the system decreases during the exploration of the solution space.
    The aim of the rescaling is to increase the distance between towns having high cost and to reduce the cost of short distance between towns.
    To obtain it I apply a "quasi" n log n function to the cost matrix.
    (A publication on the topic should be ready by the end of the year).

    Results
    All experiments as usual as been done through "home made" application written in Mathematica.
    • The cost matrix has been built  using a uniform distribution with integer values (1 to 10 for the first experiment and 1 to 100 for the second one).
    • Just to have a reference point I assigned to the cost matrix the minimum value (1) in correspondence of the external perimeter of the "town system"
    • The ATSP with 10 towns has optimal solution cost = 9. The ATSP with 50 towns has optimal solution cost = 49.
    After 2000 cycles, SA found a solution having cost = 13. (the graph on the II quadrant represents the acceptance prob.).
    The initial temperature beta has been set = 5.

    After 1000 cycles, SA with MatrixCost rescaled found the optimal solution having cost 9.
    The initial temperature beta has been set = 5.
    I repeated the same experiment increasing the initial temperature to 15.
    SA launched with beta= 15. After 5000 cycles the sub optimal solution found has cost = 14


    SA with matrix cost rescaled after 2000 cycles found better solution (same initialization of the above experiment)
    A larger test has been done to understand the statistical behavior:
    The blue line represents the solution costs of the traditional SA.
    The red line represents the solution costs of the SA with matrix cost rescaled 

    And to conclude, here you are the results obtained with higher complexity (50 towns).

    ATSP (50 towns) comparison between traditional SA and SA with rescaled matrix cost.


    Let's try to increase the number of cycles from 1000 to 3000.

    The % of success of the new strategy seems increase with the increase of the number of cycles.

    Let's see what happens increasing once again the number of cycles:

    The assumption seems to be confirmed: the new strategy performs better than the traditional SA even if the number of cycles is higher. 
    Conclusion
    1. Often the accuracy/performance of an algorithms depends on the way you feed it with the data! Rescaling your data is quite always essential!
    2. The strategy requires further tests and validation.
    ...We will discuss about the function used to rescale the matrix costs and some other application of SA on different problems in the next posts.
    cheers & stay tuned
    P.S.
    Special thx to Tom V. : he is on the top of the list of the contributors for the sponsorship program.

    Wednesday, May 23, 2012

    Outlier analysis: Chebyschev criteria vs approach based on Mutual Information

    As often happens, I usually do many thing in the same time, so during a break while I was working for a new post on applications of mutual information in data mining, I read the interesting paper suggested by Sandro Saitta on his blog (dataminingblog)  related to the outlier detection. 
    ...Usually such behavior is not proficient to obtain good results, but this time I think that the change of prospective has been positive!


    Chebyshev Theorem
    In many real scenarios (under certain conditions) the Chebyshev Theorem provides a powerful algorithm to detect outliers.
    The method is really easy to implement and it is based on the distance of Zeta-score values from k standard deviation.
    ...Surfing on internet you can find several explanations and theoretical explanation of this pillar of the Descriptive Statistic, so I don't want increase the Universe Entropy explaining once again something already available and better explained everywhere :)


    Approach based on Mutual Information
    Before to explain my approach I have to say that I have not had time to check in literature if this method has been already implemented (please drop a comment if someone find out a reference! ... I don't want take improperly credits).
    The aim of the method is to remove iteratively the sorted Z-Scores till the mutual information between the Z-Scores and the candidates outlier I(Z|outlier) increases.
    At each step the candidate outlier is the Z-score having the highest absolute value.

    Basically, respect the Chebyschev method, there is no pre-fixed threshold.

    Experiments
    I compared the two methods through canonical distribution, and at a glance it seems that results are quite good.
    Test on Normal Distribution
    As you can see in the above experiment the Mutual information criteria seems more performant in the outlier detection.
    Test on Normal Distribution having higher variance

    The following experiments have been done with Gamma Distribution and Negative Exponential
    Results on Gamma seem comparable.


    Experiment done using Negative Exponential distribution
    ...In the next days I'm going to test the procedure on data having multimodal distribution.
    Stay Tuned
    Cristian

    Saturday, May 5, 2012

    Uncertainty coefficients for Features Reduction - comparison with LDA technique

    We have already discussed about feature selection and features reduction, and all the techniques we explored were strictly related and applicable only in the text mining domain.
    I would to show you one method very powerful, easy to implement and extremely general, because it is not related to the nature of the problem.
    The method is known as coefficients of constraint (Coombs, Dawes and Tversky 1970) or uncertainty coefficient (Press & Flannery 1988) and it is based on the Mutual Information concept.


    Mutual Information
    As you know, the Mutual Information between two random variables X and Y I(X,Y) measures the uncertainty of X knowing Y, and it says how much the uncertainty (entropy) of X is reduced by Y.
    This is more clear looking at the below formula:
    I(X,Y)= H(X)-H(X|Y)
    Where H is the Entropy functional.
    As usual, I don't want enter in theoretical discussions, but I heartily recommend a deep read of the book Elements of Information Theory: In my opinion it's the best book in that field.

    Let's now rethink the mutual information as a measure of "how much helpful is the feature X to classify documents having  label L":
    I(L,X) = H(L)-H(L|X)
    So, for each label and each features we can calculate the features ranking!
    Of course you can consider the average of I(L_i,X) for each label L_i, or also more complex function over that. BTW you have to assign higher rank to the feature Xj that maximize all I(L_i,Xj).

    Uncertainty coefficient
    Consider a set of people's data labelled with two different labels, let's say blue and red, and let's assume that for this people we have a bunch of variables to describe them.
    Moreover, let's assume that one of the variables is the social security number (SSN) or whatever univocal ID for each person.
    Let me do some considerations:
    1. If I use the SSN to discriminate the people belonging to the red set from the people belonging to blue set, I can achieve 100% of accuracy because the classifier will not find any overlapping between different people.
    2. Using the SSN as predictor in a new data set never seen before by the classifier, the results will be catastrophic!
    3. The entropy of such variable is extremely high, because it is almost a uniform distributed variable!
    The key point is: the SSN variable could have a great  value but it is dramatically useless to classification job.
    To consider this fact in the "mutual information ranking", we can divide it by the entropy of the feature.
    So features as SSN will receive lower rank even if it has an high I value.
    This normalization is called uncertainty coefficient.

    Comparative Experiment
    Do you have enough about the Theory? I know that ... I did all my best to simplify it (maybe to much...).
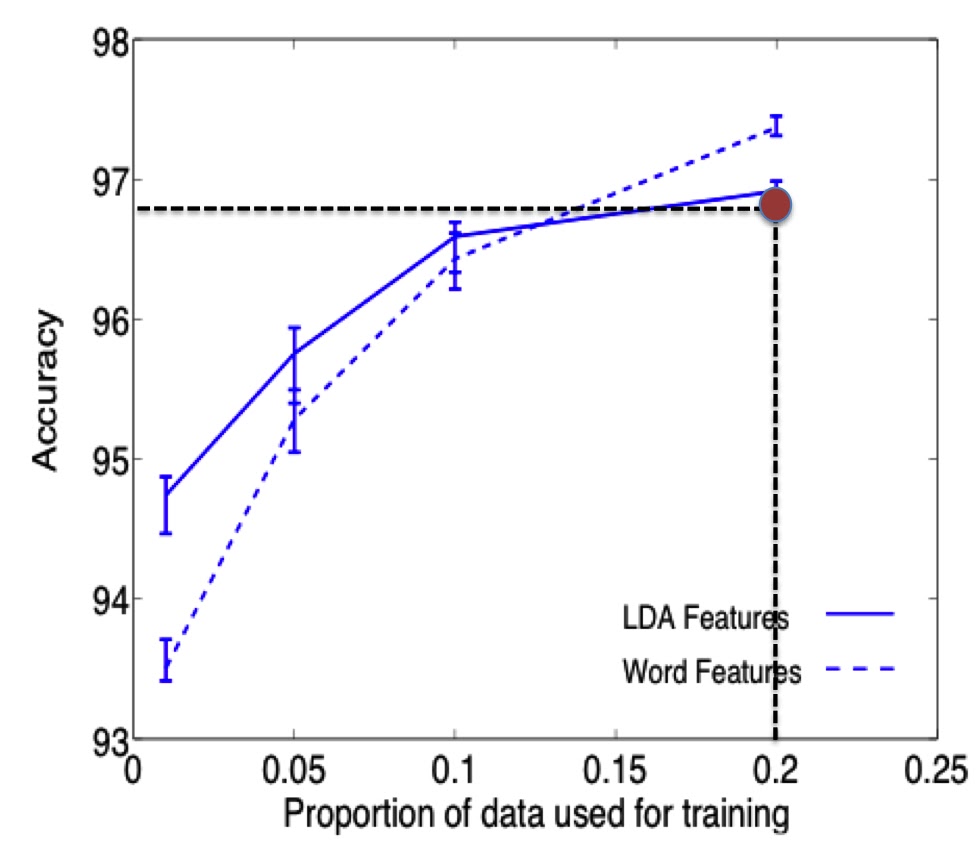
    I did some tests on the same data set used in this paper by Berkley University:
    In this test the authors did a boolean experiment over REUTERS data set (actually it is very easy test) and they compared the accuracy obtained using all the words in the data set as features and the features extracted through a Latent Dirichlet Allocation method.

    The data set contains 8000 docs and 15818 words. In the paper they claimed that they reduced the feature space by 99.6% and they used the entire data set to "extract" the features.
    Under this condition they tested using no more than 20% of the data set as training set.

    In the comparative test I focused on the second experiment mentioned: GRAIN vs NOT GRAIN.
    Here you are the process I followed:
    1. I choose as training set 20% of the docs.
    2. from the above training set I extracted (after stemming and filtering process) all the words and I used them to build the boolean vectors.
    3. I ranked the words through the uncertainty coefficient.
    4. I extracted the first 60 features: that is only 0.38% of the original feature space
    5. I trained an SVM with a gaussian kernel and very high value of C
    6. I tested over the remaining 80% of the data set.
    Before the results, let me show you some graph about the feature ranking.
    Entropy of the first 3000 features.
    The above graph shows the entropy of the first 3000 features sorted by TF-DF score.
    As you can notice, the features having low score have low entropy: it happens because these features are present in really few documents so the distribution follows a Bernulli's distribution having "p" almost equal to 0: basically the uncertainty of the variable is very small.


    Here you are the final ranking of the first 2500 features. 
    Uncertainty coefficient for all features.

    Results

    The overall accuracy measured over the test set is equal to 96.89% and it has been depicted in the below graph (I used their original graph [figure 10.b] as base) as a red circle:
    Accuracy comparison: the red circle represents the accuracy obtained training an SVM with the features extracted through the Uncertainty Coefficients.
    I would like to remark that the features has been extracted using just the training set (20% of the data set),  while the experiments done by the authors of the mentioned paper used the entire data set.
    Better results can be easily achieved using the conditioned entropies in an iterative algorithm where the mutual information is measured respect a local set of features (adding the features that maximize the M.I. of the current set of features).

    Our  experiment shows clearly that the "Uncertainty Coefficients" criteria is a really good approach!
    Soon, we will see how to use this criteria to build a clustering algorithm.  
    As usual: stay tuned.
    cristian